chatomon
Declare a chat agent once, wrap it in orbitals, and build it into the framework you already use.
Overview
chatomon ("chat" + "atom") lets you declare a chat agent once — an atom made of instructions, knowledge and a connector — surround it with orbitals that check messages going in and replies coming out, and build it into a native agent of the framework you already use. chatomon is not a chatbot framework: it never runs the agent itself; it installs checks inside PydanticAI, LangChain/LangGraph, Microsoft Agent Framework or Google ADK. Foundry PromptAgents support checked input and output on non-streaming runs.
Key Features
- One declaration, native agents —
Atom.build()returns a realpydantic_ai.Agent, LangGraphCompiledStateGraph, MAFAgentorFoundryAgent, or Google ADKApp, with the supported framework features intact. - Orbitals — ordered input and output guardrails with four outcomes: let the message through, block it with a fixed reply, block it and let the model write a guided refusal, or answer in place of the model.
- Guidance instead of hard blocks — orbitals can steer the model for one turn, or make it regenerate a reply, without the guidance ever entering the conversation history.
- Fail-closed by default — an orbital that fails or times out blocks the message unless configured otherwise.
- Guard models included — an LLM judge and wrappers for Principled Intelligence's ScopeGuard (V1 and V2) and ClaimExtractor.
- Ready-made limits — caps on message and reply length and on the number of turns, with no model call.
- Audit and privacy — a structured report for every turn, OpenTelemetry spans and logs that carry no message content unless you allow it.
- A local studio — a page on your machine to chat with an atom, watch every orbital decide, tune the orbitals and take the result back as code and as tests.
Installation
chatomon is installed with the extra of the framework you use: pip install 'chatomon[pydantic-ai]', pip install 'chatomon[langchain]', pip install 'chatomon[maf]', pip install 'chatomon[maf-foundry]', or pip install 'chatomon[adk]'. The MAF core extra needs a separate package for your chosen model provider; the Foundry extra includes its client. The Principled Intelligence orbitals need pip install 'chatomon[principled]'. The core package depends only on pydantic and the OpenTelemetry API.
Quickstart
An atom with one input orbital that turns refund requests into a guided refusal. The PydanticAI and LangChain tabs use fake models. The MAF tab uses a configured Foundry chat client from the maf-foundry extra; set FOUNDRY_PROJECT_ENDPOINT to the full project endpoint and set FOUNDRY_MODEL_DEPLOYMENT before running it. The Google ADK tab calls a Gemini model and needs your Google credentials.
from pydantic_ai.models.test import TestModel

from chatomon import Atom, Knowledge, OrbitalContext, Verdict, orbital
from chatomon.connectors.pydantic_ai import PydanticAIConnector


@orbital
def no_refunds(ctx: OrbitalContext) -> Verdict:
    if "refund" in ctx.message.lower():
        return Verdict.block(guidance="Explain that refunds are handled by email.")
    return Verdict.allow()


atom = Atom(
    name="speedypack",
    instructions="You are the customer assistant of SpeedyPack, a parcel courier.",
    knowledge=Knowledge("Opening hours: Monday to Friday, 9-18."),
    connector=PydanticAIConnector(TestModel(custom_output_text="Refunds are handled by email.")),
    input_orbitals=[no_refunds],
)
agent = atom.build()
result = agent.run_sync("I want a refund")
assert result.output == "Refunds are handled by email."
from langchain_core.language_models.fake_chat_models import GenericFakeChatModel
from langchain_core.messages import AIMessage, HumanMessage

from chatomon import Atom, Knowledge, OrbitalContext, Verdict, orbital
from chatomon.connectors.langchain import LangChainConnector


@orbital
def no_refunds(ctx: OrbitalContext) -> Verdict:
    if "refund" in ctx.message.lower():
        return Verdict.block(guidance="Explain that refunds are handled by email.")
    return Verdict.allow()


model = GenericFakeChatModel(messages=iter([AIMessage(content="Refunds are handled by email.")]))
atom = Atom(
    name="speedypack",
    instructions="You are the customer assistant of SpeedyPack, a parcel courier.",
    knowledge=Knowledge("Opening hours: Monday to Friday, 9-18."),
    connector=LangChainConnector(model),
    input_orbitals=[no_refunds],
)
agent = atom.build()
result = agent.invoke({"messages": [HumanMessage(content="I want a refund")]})
assert result["messages"][-1].content == "Refunds are handled by email."
import asyncio
import os

from agent_framework.foundry import FoundryChatClient
from azure.identity.aio import DefaultAzureCredential

from chatomon import Atom, OrbitalContext, Verdict, orbital
from chatomon.connectors.maf import MAFConnector


@orbital
async def no_refunds(ctx: OrbitalContext) -> Verdict:
    if "refund" in ctx.message.lower():
        return Verdict.block(guidance="Explain that refunds are handled by email.")
    return Verdict.allow()


async def main() -> None:
    async with DefaultAzureCredential() as credential:
        client = FoundryChatClient(
            project_endpoint=os.environ["FOUNDRY_PROJECT_ENDPOINT"],
            model=os.environ["FOUNDRY_MODEL_DEPLOYMENT"],
            credential=credential,
        )
        try:
            agent = Atom(
                name="speedypack",
                instructions="You are the customer assistant of SpeedyPack.",
                connector=MAFConnector(client),
                input_orbitals=[no_refunds],
            ).build()
            reply = await agent.run("I want a refund", session=agent.create_session())
            print(reply.text)
        finally:
            await client.project_client.close()


asyncio.run(main())
import asyncio

from google.adk.runners import InMemoryRunner

from chatomon import Atom, OrbitalContext, Verdict, orbital
from chatomon.connectors.adk import ADKConnector


@orbital
async def no_refunds(ctx: OrbitalContext) -> Verdict:
    if "refund" in ctx.message.lower():
        return Verdict.block(guidance="Explain that refunds are handled by email.")
    return Verdict.allow()


async def main() -> None:
    app = Atom(
        name="speedypack",
        instructions="You are the customer assistant of SpeedyPack.",
        connector=ADKConnector("gemini-3.5-flash"),
        input_orbitals=[no_refunds],
    ).build()
    events = await InMemoryRunner(app=app).run_debug("I want a refund", quiet=True)
    print(events[-1].content.parts[0].text)


asyncio.run(main())
Studio
The studio is a local page for trying an atom before it goes anywhere. You chat with it, watch every orbital decide while the turn runs, tune the orbitals until they behave, and take the result back as code and as tests. It is a development tool: it runs on your machine and never changes your code.
Install the studio extra together with the extra of your framework, for example pip install 'chatomon[studio,pydantic-ai]', and give the command your atom:
chatomon studio speedypack.app:atom
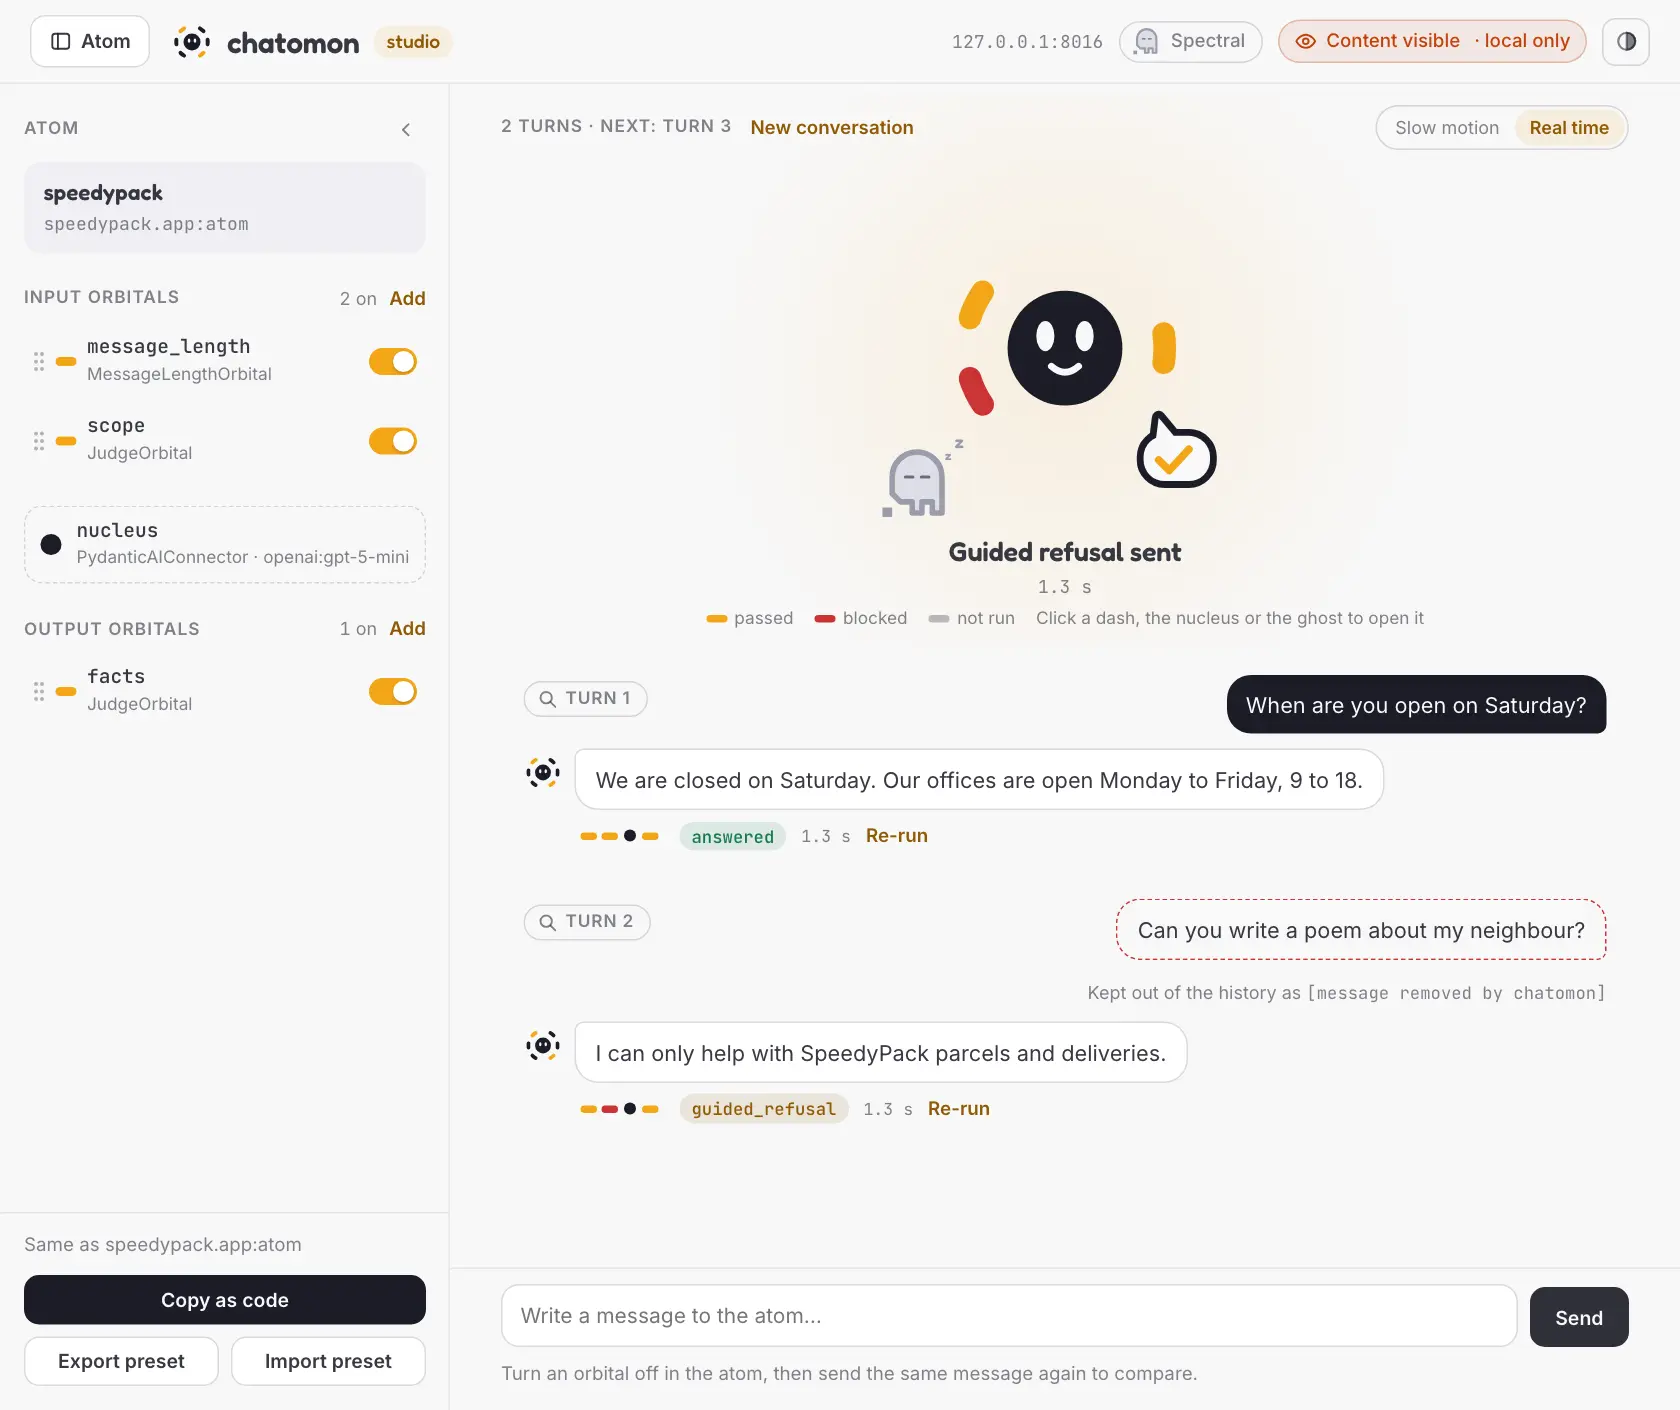
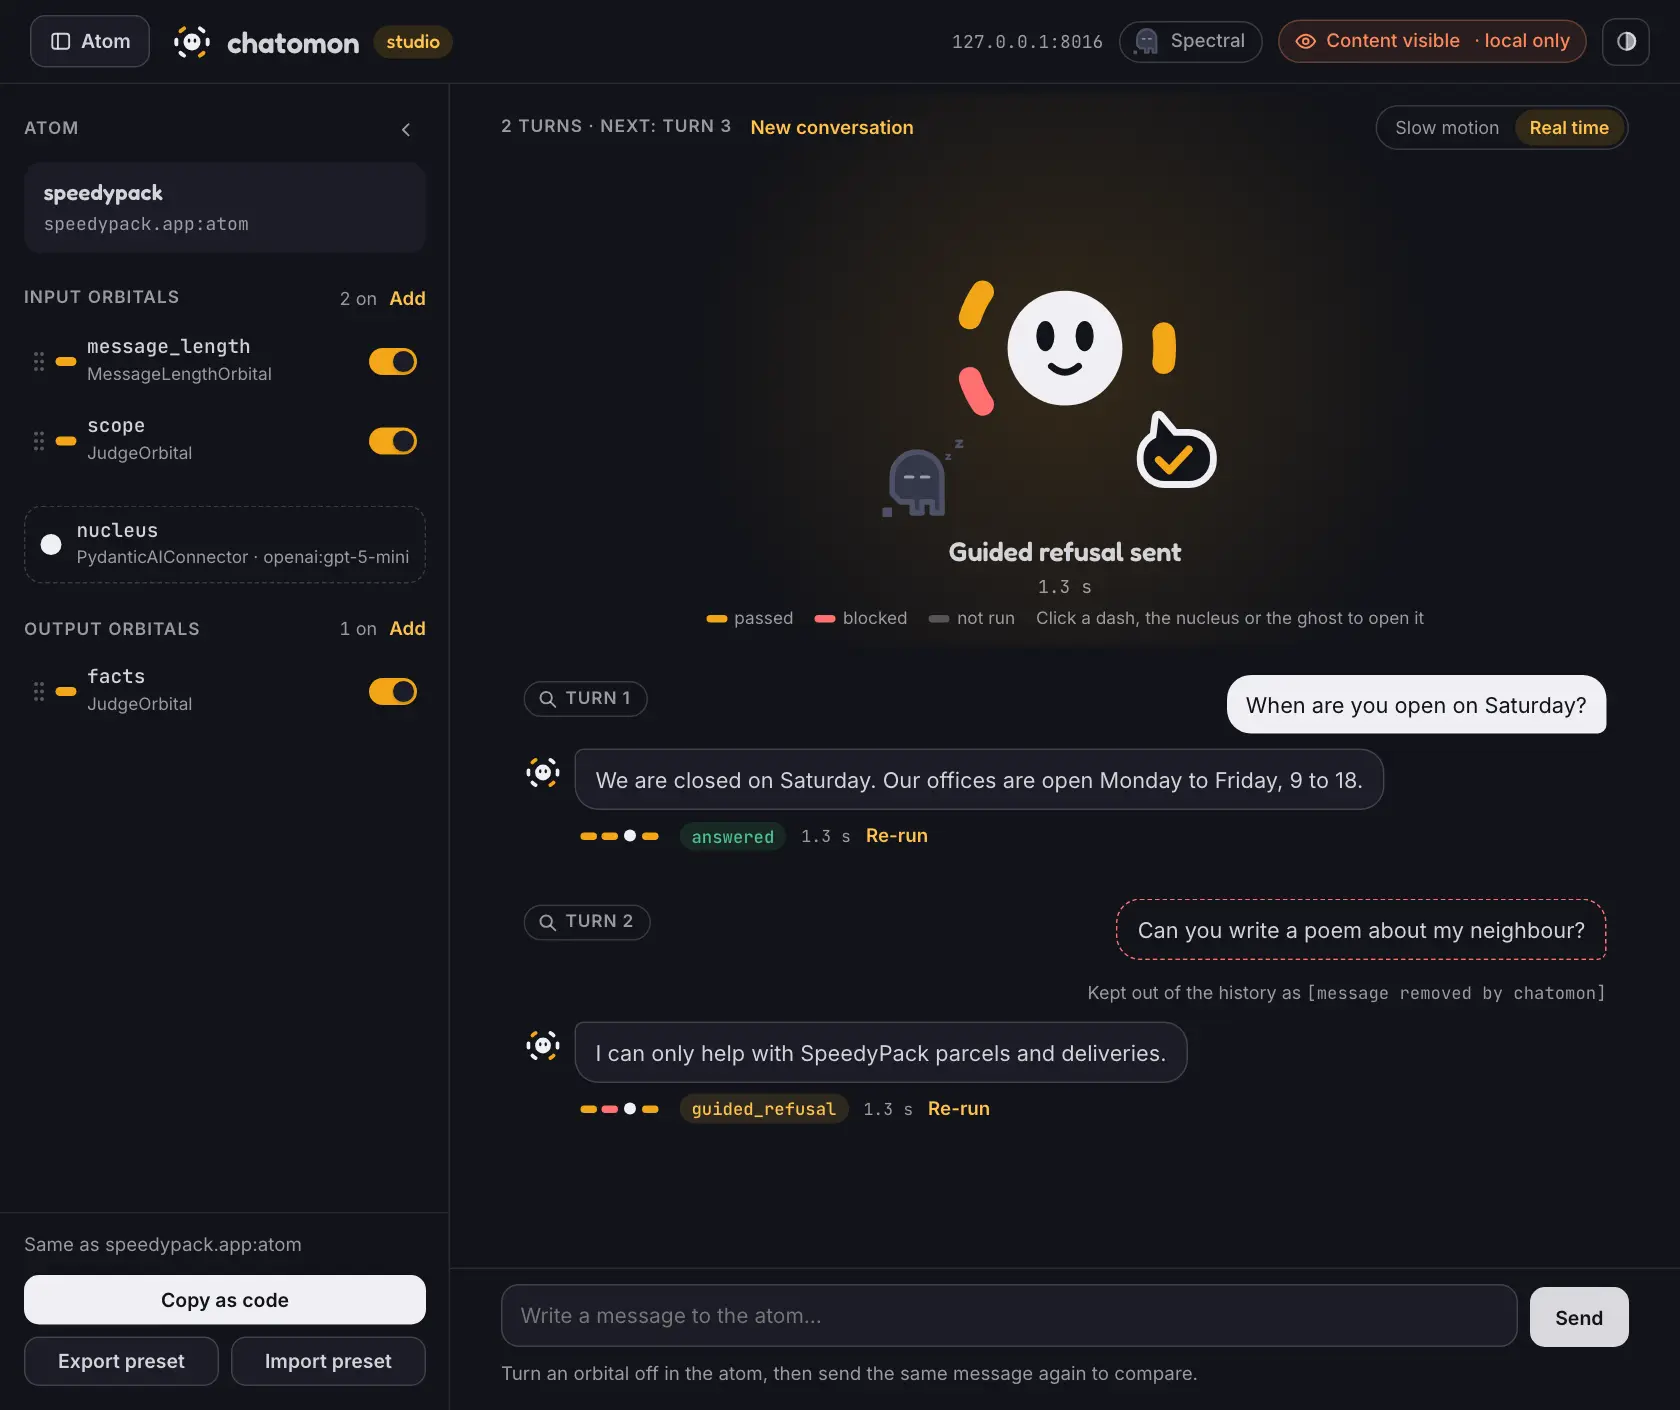
Studio explains the screen, how to tune the orbitals and how to take the result back to your code.
Table of Contents
-
Concepts
Atoms, orbitals, verdicts and what happens to a message during a turn.
-
Orbitals
Chaining and failures, writing your own, the LLM judge, length and turn limits and the Principled Intelligence guard models.
-
Connectors
How atoms become PydanticAI, LangChain, MAF and Google ADK agents: conversations, streaming, tools and tracing.
-
Observability and audit
Logs, OpenTelemetry spans, turn reports, content capture and compliance notes.
-
Studio
A local page to chat with an atom of any supported framework and watch its orbitals decide: reading the screen, tuning orbitals, taking the result back as code, as a preset or as a test, reloading your code without a restart, and what changes with each framework.
-
Deployment
Running guard models behind private, authenticated endpoints.
-
API reference
Every public module, generated from the code, with runnable examples.
The Changelog explains where release notes are published and how versions are numbered.
Key Components
| Component | Location | Purpose |
|---|---|---|
Atom |
src/chatomon/atom.py |
Declares the agent, validates the orbital chains and builds the native agent |
Knowledge |
src/chatomon/knowledge.py |
Plain-text knowledge added to the nucleus prompt |
Orbital, orbital |
src/chatomon/orbitals/base.py |
The orbital extension point and the function decorator |
Verdict, TurnReport |
src/chatomon/schemas.py |
The result of an orbital and the audit record of a turn |
Engine |
src/chatomon/engine.py |
Runs the orbital chains and turns verdicts into decisions |
PydanticAIConnector |
src/chatomon/connectors/pydantic_ai.py |
Builds atoms into PydanticAI agents |
LangChainConnector |
src/chatomon/connectors/langchain.py |
Builds atoms into LangChain agents (LangGraph graphs) |
MAFConnector, MAFFoundryConnector |
src/chatomon/connectors/maf/ |
Build atoms into MAF core and Foundry agents |
ADKConnector |
src/chatomon/connectors/adk.py |
Builds atoms into Google ADK apps |
JudgeOrbital |
src/chatomon/orbitals/judge.py |
An LLM that judges messages with its own instructions |
MessageLengthOrbital, TurnLimitOrbital |
src/chatomon/orbitals/limits.py |
Ready-made length and turn limits |
ScopeGuardOrbital, ClaimExtractorOrbital |
src/chatomon/orbitals/principled.py |
Principled Intelligence guard models as orbitals |
serve |
src/chatomon/studio/server.py |
Starts the local studio for an atom |
Related Documentation
- Concepts — start here for the mental model
- API Reference — parameters and runnable examples for every public object
Last Updated: October 2026 Status: Implemented